
Control System Backup and Restore: Shutdown Readiness Checklist
Verify PLC and DCS backups before a planned shutdown: system images, projects, configurations, credentials, restore tests, evidence, and rollback.
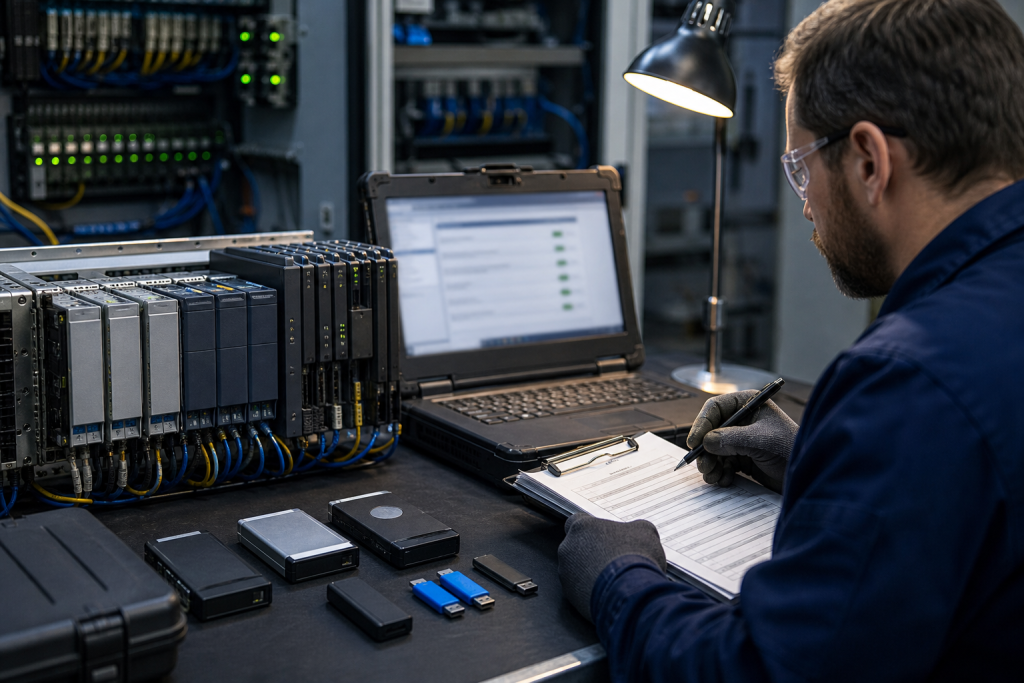
A planned shutdown is the worst time to discover that a control-system backup is incomplete. The file may exist, but the restore may depend on an old engineering workstation, a missing license, an undocumented password, a specific firmware version, or a network configuration that was never captured.
For PLC, DCS, HMI, historian, and industrial network environments, backup readiness means more than copying a project file. The maintenance team needs a known recovery state, a reproducible procedure, compatible hardware, and evidence that the process can return to a safe operating condition.
Separate the backup layers
Start by listing every layer required to recover the control system. A practical register normally includes:
- System images for engineering stations, operator stations, servers, and specialized hosts.
- PLC or DCS projects, hardware configurations, libraries, recipes, and source files.
- HMI screens, alarm databases, historian configuration, reports, and user settings.
- Device-specific data for drives, remote I/O, gateways, managed switches, and instruments.
- Network addressing, VLANs, firewall rules, time sources, certificates, and license evidence.
Siemens guidance describes system backup, project backup, and component-specific data as separate parts of a recovery strategy, and emphasizes that restore must be tested and reproducible. The same principle applies across vendors: a project backup cannot replace a host image, and a host image cannot replace a controller configuration or network repository.
When reviewing the hardware layer, use the PLC and controller collection to organize the installed processor and spare records. The actual model, firmware, revision, memory arrangement, and application remain the authority for recovery.
Record what changed since the last backup
A backup is only useful if its date and scope are clear. Compare it with the last maintenance window, software change, firmware update, network modification, instrument replacement, recipe revision, and alarm change. Ask which files changed and which systems were not included.
Do not use a file timestamp as proof of content. Open the archive in a controlled environment, check the project version, confirm that the hardware configuration matches the installed rack, and record the tool version used to create or restore it. If the project was saved from a different engineering station, capture the differences before the shutdown begins.
Make credentials and licenses recoverable
Recovery often fails because the technical files are present but the access path is not. Record where credentials are managed, who can approve access, how service accounts are restored, and which licenses or certificates are needed. Never store production passwords in an ordinary article, spreadsheet, or unprotected project folder.
Instead, link the backup record to the approved credential vault and document the authorization path. Include license files, activation information, dongles, certificates, and vendor-tool installers in the recovery inventory. Note the version and compatibility of the engineering software, especially when a legacy platform is no longer easy to download.
Back up the network and supporting devices
The controller may be healthy while the plant remains unavailable because a switch, gateway, remote I/O coupler, firewall, or time source was not restored. Capture network topology, addresses, redundancy, managed-switch configurations, media converters, fieldbus settings, and the procedure for isolating affected segments.
For drives and motion devices, store parameter sets, motor data, communication settings, feedback details, and safe restart conditions. For sensors and transmitters, record ranges, calibration data, process connections, scaling, and alarm limits. The communication modules and I/O collection and variable-frequency inverter collection can help structure the hardware dependencies in the recovery list.
Test restore before the outage
The most important step is a restore test. Where the process allows, use a spare controller, test rack, virtual machine, isolated workstation, or staged network. Restore the system image, project, hardware configuration, device files, and network settings using the same sequence intended for an outage.
Check controller startup, I/O diagnostics, communications, HMI screens, alarm routing, historian tags, recipes, time synchronization, redundancy transfer, and loss-of-communications behavior. For safety-related functions, follow the site’s approved validation and change-control process rather than relying on a simple power-up.
Record the restore duration and every manual step. If a part is needed, link it to the exact spare record and confirm that the spare is tested, correctly stored, and compatible with the recovered project. A restore test that cannot be completed without an unavailable module is valuable evidence of a coverage gap.
Keep evidence that another engineer can follow
A recovery pack should contain the date, system scope, backup identifiers, firmware and software versions, screenshots or logs of successful checks, open limitations, approver, and the next review date. Store it where the outage team can reach it even if the normal engineering workstation or plant file server is unavailable.
Use clear status labels: verified restore, partially verified, archive only, expired, or blocked by missing dependency. Do not call an archive “ready” simply because it opens on a laptop. The test must demonstrate that it can reconstitute the required control function.
Write the shutdown acceptance criteria
Before the maintenance window, agree what “ready to restart” means. Criteria may include controller health, I/O checks, alarm visibility, operator graphics, recipe access, historian continuity, drive operation, instrument calibration, network redundancy, and documented rollback.
Define who signs each check: automation, electrical, operations, quality, safety, or IT/OT security. Keep the acceptance record with the change ticket and update the backup register after the work. A new backup should be created after any approved configuration change.
FAQ
Is copying the PLC project enough?
No. Recovery may also require the hardware configuration, firmware, libraries, engineering software, licenses, HMI, network, device settings, and compatible spare hardware.
How often should a control-system restore be tested?
Set the interval according to criticality and change frequency. Test after major software, firmware, network, or hardware changes, and repeat periodically so the procedure does not depend on one person’s memory.
Can a virtual machine replace a physical recovery test?
It can validate some host software and project layers, but it may not prove controller firmware, I/O wiring, fieldbus timing, safety behavior, or physical network dependencies. Use the test method that matches the failure modes.
What should be done when the restore test fails?
Record the exact failure, classify the missing dependency, assign an owner, and update the spare or migration plan. Do not hide the failure by labeling the archive as verified.
Make recovery part of spare planning
SmartNexMSK can help organize controller, I/O, drive, network, configuration, and spare evidence for a planned shutdown or legacy system review. Send model numbers, label photos, backup scope, quantity, destination, and the maintenance window to [email protected] or WhatsApp/Phone +86 18259474341.
Route this topic into a sourcing request
Connect the article topic to a model number, category, brand, quantity, and destination before opening the RFQ.
Related Insights
Continue with sourcing and model matching guides
 Sep 8, 2026
SANYO DENKI QS1E Spares: Save Parameters First
When a SANMOTION Q axis stops, the purchasing request often becomes a model number: “Please quote QS1E01AA0H4A3P1T.” That is a useful starting point, but…
Read guide Sep 6, 2026
Yaskawa SGDH-05DE-OY Spares: Check the Servo Chain
A servo drive fault often produces a deceptively simple purchasing request: “Replace the SGDH-05DE-OY.” In a running machine, however, the amplifier is only one…
Read guide Sep 5, 2026
GE IS220PCLAH1A Spares: Check Mark VIe Fit
When a Mark VIe cabinet develops an intermittent control fault, the urgent request often becomes a single line: “Please quote IS220PCLAH1A.” That is understandable…
Read guide